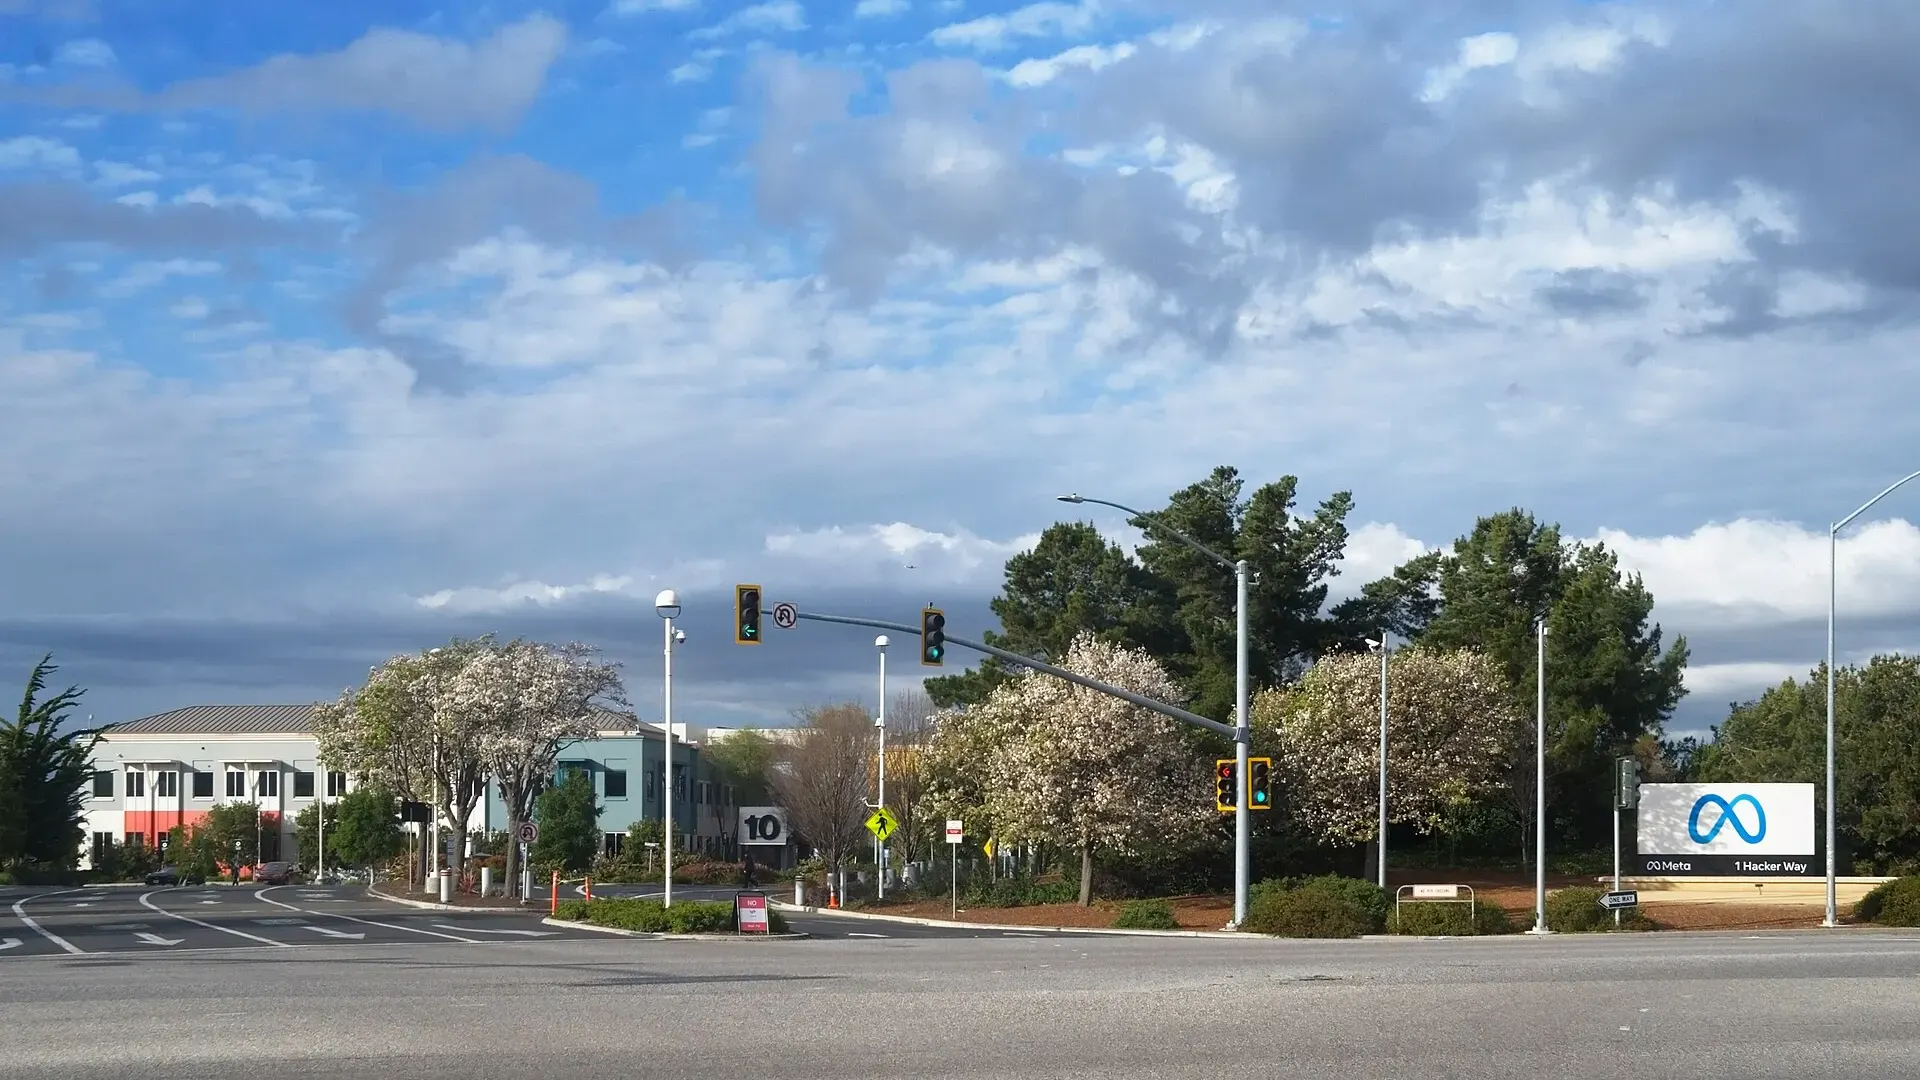
MENLO PARK, California — Meta has deleted the word "train" from new commercial terms that would have let it feed content scraped from business customers' websites into its artificial intelligence models, after two days of protest from news publishers on both sides of the Atlantic.
The revision, published on Friday afternoon, narrows the stated purpose of Meta's web crawling to "advertising and business products" rather than all Meta products, Nieman Lab reported. The terms still take effect on October 30, and legal experts who reviewed the new wording said it continues to authorize broad scraping of any site linked to a business account on Facebook, Instagram or WhatsApp.
The episode matters because almost every news organization, retailer and small business runs a Meta business account, and the terms give them no way to opt out short of leaving the platforms. Publishers have spent two years trying to force AI developers to pay for training data, and a clause buried in business terms threatened to hand Meta that material for free.
Nieman Lab first reported the change on Thursday. The original text said Meta "may use any content from such domains, web pages, or URLs to provide, develop, improve, research, train, and maintain the integrity of" its products and services. Three legal experts consulted by the outlet said the language could be used to argue that Meta may scrape news sites and use the content to train its AI.
"This is a remarkable provision to bury in the terms of service, given that this would give Meta access to material that would likely cost many millions of dollars in a licensing market," Matt Topic, a media and intellectual property lawyer at Loevy & Loevy, told Nieman Lab at the time.
Meta said the clause had been misread. "We've heard you and want to clarify: the crawling terms we consolidated only applied to our ads and business products, and we've clarified that in the terms themselves," a spokesperson said, adding: "This is not about scraping news sites, and these updates don't give us new rights that supersede those preferences."
The company told TechCrunch the update "does not change how Meta uses web crawlers." On Saturday a spokesperson told Nieman Lab the terms were revised because "it wasn't clear in the initial consolidation of terms that robots.txt preferences are respected," and that news sites "still have the ability to disable the crawler via robots.txt flags."
The revised terms do not mention robots.txt, the file that tells bots which parts of a website they may visit, according to Nieman Lab. Benjamin Sobel, a law professor at the University of Wisconsin, said compliance with such files is voluntary. "You can still express the preference, and unless it's a legally enforceable preference, it can still be ignored all the same," he said.
Topic said the rewrite changed less than it appeared to. "I think publishers should remain concerned," he said. "I think 'develop' is broad enough to include 'train.'"
James Grimmelmann, a professor of digital and information law at Cornell Law School, said the update "doesn't address my concerns," describing the permission to develop advertising and business products as "still broad enough to drive a truck through."
Meta's existing terms already allowed it to scrape websites tied to business accounts, but only when those accounts used its generative AI advertising tools, and only to "optimize your ads," Nieman Lab reported. Extending that permission to all advertising and business products, which Meta lists as "ads, Meta Business Tools and Meta Business Suite," is a substantial expansion, the outlet said.
The clause also lets Meta create "test credentials" to access sites. Grimmelmann said that would allow the company to sign up as a fake user to get past registration walls. Meta declined to tell Nieman Lab whether such credentials could bypass paywalls.
Trade groups moved fast. The European Publishers Council said it would petition EU telecoms regulators and the European Commission to "scrutinize these terms urgently, including their implications for copyright, contractual fairness and abuse of market power."
In Britain, the News Media Association called for ministers to intervene. Chief executive Theo Bamber described the terms as "the worst kind of arrogant tech platform bullying."
Danielle Coffey, president and chief executive of the News/Media Alliance in the United States, called the update "outrageous and probably illegal." She said: "It cannot be allowed to be implemented on October 30."
There is also confusion over what Meta has published. PPC Land reported on Saturday that the UK English edition of Meta's preview page for the new terms still contained the original training sentence at 20:44 UTC, a day after The Verge reported it had been removed.
The fight sits inside a wider legal battle over AI training. Five large book publishers filed a class action in May accusing Meta of pirating millions of books to train its Llama models, according to Nieman Lab, while Meta won a separate copyright case over books last year, TechCrunch reported.
Businesses that do not accept the new terms have been told to "stop all access or use of our Products for business or commercial purposes." The terms, in whatever final form Meta publishes, become binding on October 30.
Sources
- Legal experts warn Meta's new terms still grant broad scraping permissions, despite language changes (niemanlab.org)
- Meta's new commercial terms will allow the scraping of news sites, legal experts say (niemanlab.org)
- Meta removes language that raised scraping and AI training concerns (techcrunch.com)
- Meta's AI training clause still in Oct 30 terms after report of removal (ppc.land)
- Meta removes terms that raised concerns over website scraping and AI training (medianama.com)
This report was compiled from the publicly available reporting listed above. Direct quotations are reproduced as published by those outlets. Corrections: see our corrections policy.